Category: software development

  • Get Rid of Estimation

    Software estimation. Ah, a never-ending story. Chances are good that, whenever you’re talking about building software, this subject will pop up soon. You can be pretty sure that basically everyone around has problems with estimation or simply struggles with it. And that’s virtually obvious that there would be a new sexy method of estimation every year or so. The method which is claimed to solve an unsolvable puzzle.

    Recently there was yet another question on estimation on Project Management StackExchange. This sole fact isn’t probably worth writing a whole blog post about that, but there was one side thread which is worth focusing at.

    One of advices I shared was that whenever you can you should avoid estimation at all. This sprung sort of objection. OK, so the subject definitely is worth wider discussion.

    First things first. Why do we estimate at all in the first place? Well, we usually want to know how much time it’s going to take to build this damn thing, don’t we? Um, have I just said “usually?” Meaning, “not always?” Actually yes. It’s not that rare when we either don’t need any estimate at all or we just want to have a general insight whether the project will be built in hours, days, weeks, months or years. In either of these cases just a coarse-grained wild-ass guess should be fine. If it’s needed at all.

    OK, but what about majority of cases when we need some kind of real estimate? For example all those fixed price projects where estimates are basically a part of risk management, as the better the estimate is the smaller are chances that the project goes under water. I can’t deny that we need to have something better than wild-ass guess then.

    Yet, we still can avoid estimating quite often.

    Let me start with one of obvious things about estimation: if you base on historical data, and you apply them in a reasonable way of course, you can significantly improve your estimates. In other words, no matter the method, if you are just guessing how much something is going to take, you will likely to end up with way worse results when compared to a method, which uses your track record. And yes, I just dared to name planning poker “guessing.” It is collective, involves discussion, etc but usually it is just this: guessing.

    Cool, let’s use historical data then. What’s next? My next question would be: how precise must your estimates be? Seriously, what kind of precision you aim for? My point is that we need very precise estimates very rarely. This is by the way the reason why I don’t use Evidence Based Scheduling anymore.

    Anyway, ask yourself a question: how much you would pay for bringing your estimates to the next level of precision. Think of it like being correct in terms of estimating in years, months, weeks, days, hours, etc. Let’s take just an average several-month-long, fixed-priced type of project.

    If I’m wrong with years I’m totally screwed, thus I’d pay significant part of project budget to be correct on such level. If I’m wrong with months it might be a hit on our reputation and also it may consume our whole profit we get of the project, so I’d be ready to invest something around the profit to be correct with months. Now weeks. Well, a week here, a week there, does it make such a difference in this kind of project? Can’t I just assume there is some variability here? Unless of course our deadlines are written in stone, e.g. you adjust your software to law changes. In most cases I’d invest just a handful of bucks here at best. Days? Hours? Are you kidding? Does it even make a difference that I spend a day more on such project?

    Now you know what kind of precision you expect from your estimates. Would it be possible for you to come up with estimates of such precision basing purely on historical data? I mean, can’t you just come up with a simple algorithm which automatically produces results reasonable enough that you can forget about all the effort spent on estimation?

    Whenever we come to discussing estimation I like to share the story from one of my teams: basing on a fact that we were collecting data on our cycle times and we reduced variability in task sizes coming up with the idea of standard-sized features we were able to do a very good job with estimates not estimating at all. We were simply breaking work down so we could learn how many features there are to build and then we were using very simple metrics basing on our track record to come up with the numbers our sales department requested. By the way: a funny thing is, almost all of that appeared as an emergent behavior – something we started doing as a part of continuous improvement initiative.

    Either way, even though we were capable of providing reasonably precise and reliable estimates we didn’t really estimate. I was surprised how easy it was to get rid of estimation, but then I can come back to the point from the beginning of the article: what is the point of estimation? You don’t do it just for the sake of performing the task; you do it for a reason. As long as you achieve your goal, does the method really matter? It means that you can get rid of estimating even if you do need some kind of estimates.

  • When Kanban Fails

    In my story from Lean Kanban Central Europe 2011 I promised I will elaborate more on my session there, titled Kanban Weak Spots. The starting point to the session was analysis of a number of situations where Kanban didn’t really work, finding out a root cause and then trying to build a bunch recurring patterns from that.

    By the way I have an interesting observation. Whenever I called for Kanban failure stories I heard almost perfect silence as an answer. It seems everyone is so damn good with adopting Kanban that it virtually never fails.

    Except I’ve personally seen a bunch of failed Kanban implementations. Either I’m the most unlucky person in the world and saw all of Kanban failures out there or for some reason we, the Kanban crowd, are still sharing just success stories and not putting enough attention to our failures.

    Actually, when I was discussing the session with fellow presenters we quickly came to the point that basically every time we think about Kanban failures it can be boiled down to people. However, and it is one of recurring lessons from lkce11, we should address vast majority of ineffectiveness to the system, not to the people. In other words, yes, Kanban fails because of people, but we change the system and only this way we influence people behavior.

    This is exactly the short version of the presentation, inspired by Katherine Kirk and Bob Marshall.

    There is the long version too. Symptoms, which show you that something isn’t working, and if you do nothing about them you’re basically asking for failure. I have good news though. Most of the time you will look for these symptoms in just one place – on your Kanban board.

    Probably the most common issue I see among Kanban teams is not keeping the board up to date. In short, it means that the board doesn’t reflect the reality and your team is making their everyday project decisions basing on a lie. A very simple example: given that there is a bottleneck in testing but it isn’t shown on a Kanban board, a developer would come to the board to see what’s next and they would decide to start building a new feature instead of helping to sort bottleneck out. Instead of making things better they would make them even worse, thanks to the board which isn’t up to date.

    I face the same problem but on a different level, whenever a team tries to make a board showing the way they’d like to work, and not the way they really work. Actually this one is even worse – not only do you make your everyday decisions basing on a lie again but it’s also more difficult to get things back on the right track again. This time it’s not enough to update the sticky notes – you need to fix the design of the board too.

    Another board-related issue would be forgetting about a good old rule: KISS. When people learn all these nice tricks they can use on their boards they’re inclined to use a lot of them. Often way too many. They end up over-engineering the board, which means that they bury important information under the pile of meaningless data. Soon, people aren’t able to tell what means what and which visual represent which situation. Eventually, they stop to care to update the board because they’re basically lost, so they’re back to the square one.

    Violating limits has its own place in hell. Of course it is a matter of your policies whether you allow abusing limits at all. However it is pretty common situation that it is generally acceptable that limits are violated very often, or even all the time. Now, let me stress this: limits in Kanban are the fuel of improvements; if you don’t treat your limits seriously you don’t treat improvement seriously either. Limiting work in progress is a mechanism, which makes people act differently than they normally would. When a developer, instead of starting to build another feature, goes to help with a blocker in testing it is usually because limits told them so. Eventually they learn to predict such situations and act even earlier, before they fill up the work queue. Anyway it all starts with simple actions, which are triggered by limiting WIP.

    The interesting thing is that all these problems can be seen on a Kanban board. The reason is pretty simple: the board should reflect the reality, no matter how sad the reality is. You deal with lousy process the same way as you deal with alcoholism: the first step is admitting you have a problem. Even if your process looks like a piece of crap show it on your Kanban board. Otherwise you’re just cheating yourself and you aren’t even starting your journey with continuous evolution toward perfection.

    There is however one driver of Kanban failure, which won’t be seen on a Kanban board. It’s also my recent pet peeve. Treating Kanban as a project management or a software development approach is basically begging for failure. It is asking Kanban to deal with something which it wasn’t designed for. It’s using a banana to hammer a nail. Seems funny indeed, but if you care about a success, well, then good luck – you’re going to need a lot of it.

    Kanban can be called change management approach or process-driving tool or even improvement vehicle but it doesn’t say a word on how you should manage your projects or build your software. If you don’t build Kanban on a top of something, be it a set of best engineering practices or project management method of your choice, you’re likely to fail miserably. And then you will be telling everyone that you need to have experienced team to start using Kanban and that it wouldn’t work otherwise.

    So here it is – a handful of risks you should take into consideration whenever adopting Kanban in your team. A bunch of situations observed by the most unlucky guy in the world, who actually sees Kanban failures on occasions. However, what I want to achieve with this post is not to discourage you to try Kanban out. Pretty much the opposite. I want you to think of this list and actively work to avoid the traps. I just want you to succeed.

    And this is why you will hear me writing and speaking about Kanban weak spots again.

    Now, even though I teased much of the content from my lkce11 session above, here are my slides.

    By the way, if you happened to be on my session in Munich please rate it.

    If you’d like to see some more content on the subject, fear not. As I’m very passionate about that I will definitely write more on this soon.

    Advertisement: Want to have such nice Kanban boards in your presentations or blog posts as well? Check InfoDiagram Kanban Toolbox. Use pawelBBlog code to get $10 discount.


  • Good Enough

    My friend asked me to give an opinion about design of application his company had developed. I took a glimpse on their technical presentation with a lot of screenshots. I must admit my attitude was very positive, whole thing looked professionally. That’s what I told my friend. His answer was a bit surprising as he said he would have worked more on UI design. On the beta stage? It was really good enough. Or even better enough.

    The discussion brought me to think about good enough paradigm in software business. One side believes that if software is good enough the job is done. Another wants to polish all the details until they bring their software into perfection. Although I haven’t seen any statistics about that I believe the former group is more numerous one.

    Software constantly conquers new areas of our life including those where there’s hardly place for good enough believers. Hospitals, planes, cars or military areas. I guess you wouldn’t be happy if your good enough software managing your car brakes crashed. Yet still most software which is developed is not mission-critical products. It just sends e-mails, creates documents, pass information, manage some content, store some data etc. There’s a choice between good enough and close to perfection.

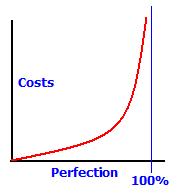
    Personally, I’m a good enough guy. I have just one point here. Costs. Imagine a theoretical scale of perfection of software ranging from 0% to 100%. When you start your development you’re in 0% when you finish you’re somewhere in upper half of the scale. On the beginning improvements are easy. You invite first test UI which looks like it was designed by blind monkey. Then you have first iteration of target UI. It’s a huge improvement, probably a couple of dozens percents on the scale. However, when you’ve already made several iterations with UI and it looks decent the next would be probably making extensive usability testing. It’ll take much more effort than the first steps. Results will be probably much less significant. Few percent if you’re lucky. Next step? Maybe user feedback? You employ a number of people, who deal with all e-mails and phones from users, than trying to find a schema in all that mess, then verifying if accidentally some requests are not exactly opposite to others etc. More effort. More money. Results limited. Maybe another percent earned on the scale.

    The example says about UI, but the rule is general. First performance optimizations will be fast and effective, unless you do them randomly. After some successes they’ll become harder and more costly. On the beginning of stabilization you’ll deal with big numbers of issues vastly improving stability of software. On the end the whole deployment will wait for a single bug fix. Of course that’s not a paradigm – there’re exceptions. Sometimes you can find some easy improvements even when you’re high on the scale, but it shouldn’t happen very often.

    That’s why I’m a “good enough” believer. I don’t refuse to make small improvements, even when users can live without them. They’re welcome as far as they’re cheap. Great example was described by Basecamp team. Those changes are close to border separating good enough from better (hard to say on which side they are), but they were quick and cheap. And I guess the more important improvements were done earlier. If the changes were significantly more expensive I think 37signals would leave it as it was.

    I believe that unless you have much time and money to spend you shouldn’t chase the ideal. There’re more important things to do.